Data Curation
Data curation is the ongoing process of organizing, validating, documenting, and maintaining reliable datasets for machine learning and evaluation.
Data curation is the ongoing process of selecting, organizing, checking, documenting, and maintaining data so it remains useful for a specific purpose. In machine learning, it shapes the examples a model learns from and the evidence used to evaluate it. A curated dataset combines relevant samples, consistent labels for supervised tasks, contextual information, and traceable versions.
Curation, Cleaning, and Preprocessing#
Curation spans the dataset lifecycle. Data cleaning corrects errors and removes unusable records; data preprocessing transforms inputs through operations such as resizing or normalization. Data annotation, also called data labeling, adds the targets used in supervised learning. Curation coordinates these activities while deciding which samples belong, how categories are defined, and how the collection changes over time. Consistent category definitions and labeling rules help models learn reliable relationships between images and targets.
This makes curation a practical component of data-centric AI, which improves systems by improving their data.
How Data Curation Works#
The process starts with a dataset specification: the prediction task, target categories, operating conditions, and inclusion criteria. For object detection, this includes rules for bounding boxes and partially visible objects. Reviewing category frequencies and capture conditions exposes dataset bias, including underrepresented classes or environments.
Quality checks combine automated inspection with human review. File checks find unreadable images; annotation checks identify invalid coordinates and inconsistent classes. Exact-file hashes detect identical copies, while embeddings—numerical representations of image content—help locate visually similar samples. Review separates repairable errors from unusable records and retains valid, difficult examples that represent the task.
A file-hash audit can retain one path per unique file. This example checks images bundled with the ultralytics package, installed with pip install ultralytics:
from hashlib import sha256

from ultralytics.utils import ASSETS

paths = sorted(ASSETS.glob("*.jpg"))
unique = {}

# Keep the first image path for each file digest.
for path in paths:
    digest = sha256(path.read_bytes()).hexdigest()
    unique.setdefault(digest, path)

curated = list(unique.values())
print(f"Before: {len(paths)}, after deduplication: {len(curated)}")
The counts show how many files remain after exact deduplication; equal counts indicate all sampled files have distinct hashes.
Splitting protects the independence of training data, validation data, and test data. Nearby video frames share scene content, so distributing them across splits introduces data leakage and inflates evaluation scores. Grouping by recording session, camera, or site makes evaluation reflect the intended generalization task. A fixed dataset version preserves those assignments alongside its labels.
Ultralytics Platform supports curation with class-distribution charts and image clustering that surface coverage gaps, duplicates, and outliers. Its dataset management tools let teams inspect these groups and update images, labels, and split assignments.
What a Data Curator Does#
A data curator maintains the collection's meaning and usability. Responsibilities include documenting sources, coordinating annotation guidelines, resolving labeling disagreements, and recording changes. Metadata—information describing the samples—captures acquisition time, sensor, location, and annotation status. Maintaining reusable data includes preserving descriptions and supporting documentation.
Data provenance records where samples originated and how they were transformed. Connecting dataset versions to experiment tracking makes model comparisons reproducible. Following deployment, active learning prioritizes informative samples for review; monitoring detects data drift, which can prompt new collection.
Examples in Computer Vision#
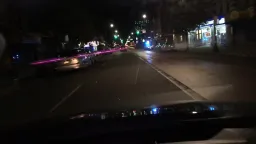
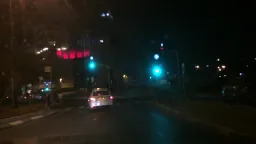
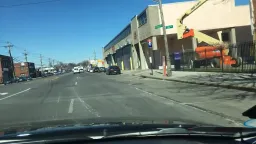
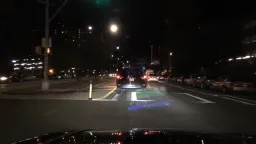
In automotive perception, the original BDD100K collection contains 100,000 driving videos spanning US locations, weather conditions, and daytime and nighttime settings. Its environmental attributes support evaluation across capture conditions. The Platform edition contains 99,996 keyframe images for detection.
 BDD100K preview 1
 BDD100K preview 2
 BDD100K preview 3
 BDD100K preview 4
Dashcam frames from crowdsourced US drives across cities, weather, and times of day, from UC Berkeley's BDD100K driving benchmark. Keyframes come from 40-second videos recorded largely in New York and the San Francisco Bay Area through Nexar, including night, rain, snow, and fog. Source: Yu, Chen, Wang, et al., "BDD100K: A Diverse Driving Dataset for Heterogeneous Multitask Learning," CVPR 2020; bdd100k.com. Free for educational, research, and non-profit use; commercial use requires UC Berkeley permission.
For image classification, the ciFAIR correction replaced near-duplicates in the original test sets of CIFAR-10 and CIFAR-100. Matches to training images or other test images affected 3.25% and 10% of their original test sets, respectively. With training unchanged, ResNeXt-29 (8x64d) classification error rose from 3.56% on CIFAR-10 to 3.95% on ciFAIR-10.









