Computer Vision (CV)
Computer vision (CV) is the AI field that lets machines interpret images and video. Covers how it works, core tasks, applications, and challenges.
Computer vision (CV) is the field of artificial intelligence (AI) that enables computers to extract meaning from images, video, and other visual data: which objects are present, where they are, how they move, and what is happening in a scene. Modern systems learn these skills from examples. A model trained on thousands of labeled images learns the visual patterns that define a car, a crack, or a tumor and applies them to images it has never seen, which is why the field now rests on machine learning (ML) and, above all, deep learning (DL).
How Computer Vision Works#
To a computer, a color image is a grid of numbers. A 640×480 photo holds 921,600 values, one per pixel for each of three color channels, each an intensity from 0 to 255. A computer vision pipeline turns that grid into a decision in five stages.
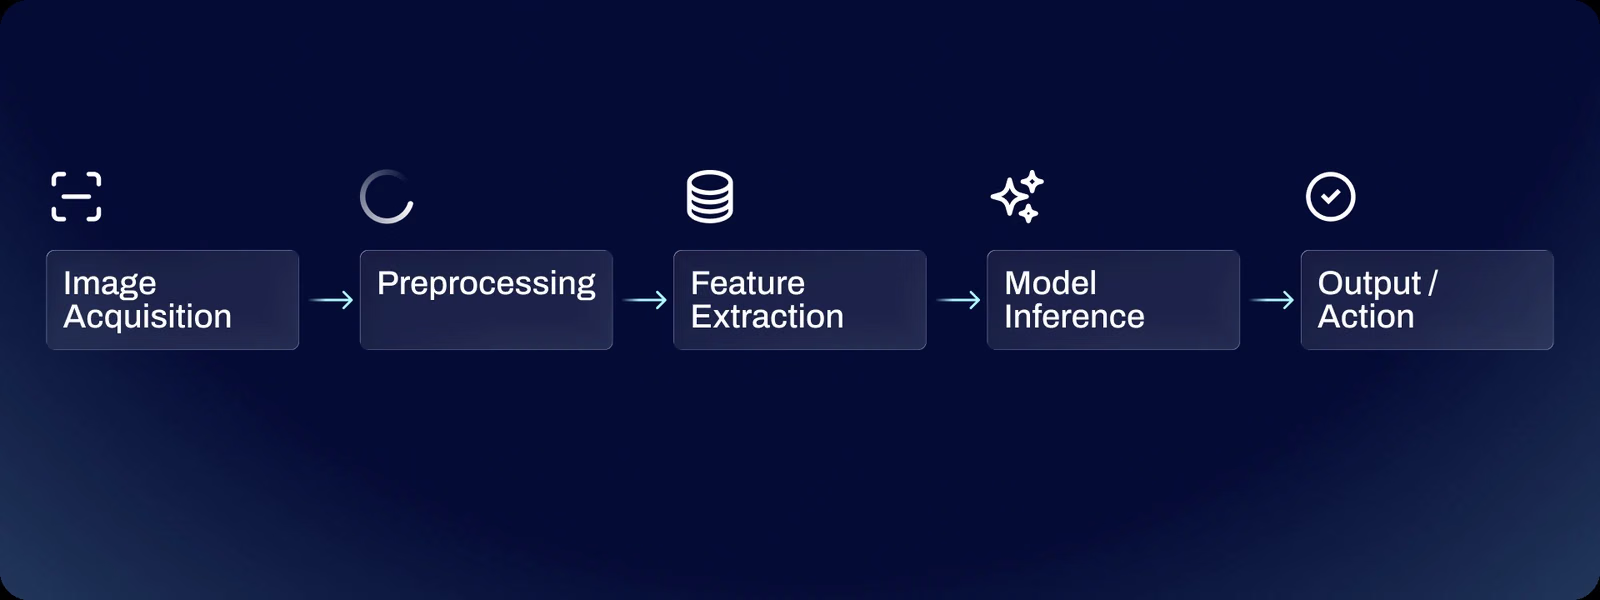
A camera or sensor captures the image, and preprocessing, often with OpenCV, resizes and normalizes it so the model always receives input in the same format. The model then performs feature extraction: the early layers of a convolutional neural network (CNN) respond to edges and color gradients, middle layers combine them into textures and parts, and deep layers respond to whole objects. Vision Transformers (ViTs) reach similar representations by splitting the image into patches and relating every patch to every other one with self-attention. A task-specific head converts the features into the output, such as a class label, a set of bounding boxes, or a pixel mask, and the surrounding system acts on it by rejecting a defective part, braking a vehicle, or raising an alert.
Models learn these features through supervised learning. During training, the model predicts on labeled images, a loss function measures how far each prediction is from the ground truth, and backpropagation adjusts the weights to shrink that error. Large public datasets such as ImageNet, with over 14 million labeled images, and COCO, with 80 everyday object categories, supply the pretraining that most custom models start from through transfer learning.
From Hand-Crafted Features to Deep Learning#
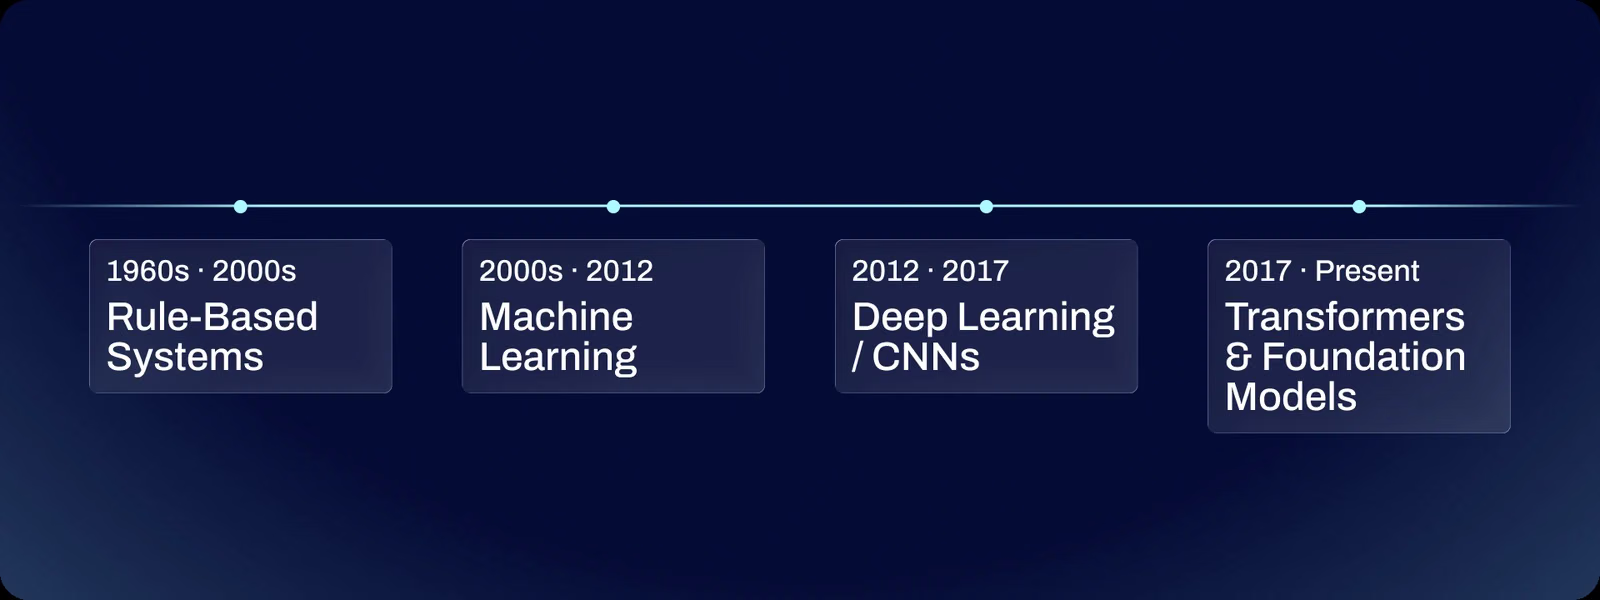
Early computer vision relied on features designed by hand. Engineers wrote detectors for edges, corners, and gradient patterns such as SIFT and HOG, then passed those features to a classifier, and the resulting systems broke whenever lighting, viewpoint, or background changed. The turning point came in 2012, when AlexNet won the ImageNet challenge with a top-5 error rate of 15.3%, against 26.2% for the next-best entry. Since then, CNNs and, from 2020, Vision Transformers have learned their features directly from data. Vision language models (VLMs) now pair images with text, so one model can answer open questions about a photo or find objects described in plain language. The VLM Leaderboard measures how accurately these models detect objects in real-world datasets.
Core Computer Vision Tasks#
Each task answers a different question about an image:
- Object detection: finds each object and draws a box around it with a class and a confidence score, which makes counting and locating possible.
- Instance segmentation: gives each object its own pixel mask, so two people standing side by side stay separate.
- Semantic segmentation: labels every pixel with a class, such as road, sidewalk, or sky.
- Depth estimation: predicts how far each pixel is from the camera, from a single image.
- Image classification: assigns one label to the whole image, such as "defective" or "OK".
- Pose estimation: locates keypoints such as body joints to measure posture and movement.
- Oriented bounding boxes (OBB): fits rotated boxes to objects at arbitrary angles, such as ships and aircraft in satellite imagery.
- Object tracking: links detections across video frames so each object keeps a consistent ID.
Choosing a task starts from the output the application needs:
Ultralytics YOLO26 covers seven of these tasks with one Python API: the same YOLO() call loads a detection, instance segmentation, semantic segmentation, depth, classification, pose, or OBB model, and model.track() adds tracking on video. This example runs object detection on a sample image:
from ultralytics import YOLO

# Load a pretrained YOLO26 nano detection model
model = YOLO("yolo26n.pt")

# Run inference on a sample street image
results = model("https://ultralytics.com/images/bus.jpg")
result = results[0]

# Print a count of detected objects per class and save the annotated image
print(result.verbose())
result.save(filename="bus_detections.jpg")
The printed line counts the detections per class, and the saved image draws each one with its box, label, and confidence score.
Computer Vision vs. Related Fields#
- Image processing: transforms an image into another image by sharpening, denoising, resizing, or adjusting contrast. Computer vision pipelines use these operations as preprocessing before interpreting the scene.
- Machine vision: the industrial application of computer vision to inspection and robot guidance, usually with fixed cameras, controlled lighting, and dedicated hardware on a production line.
- Image recognition: a common synonym for image classification, sometimes used loosely for any task that identifies what an image contains.
Real-World Applications#
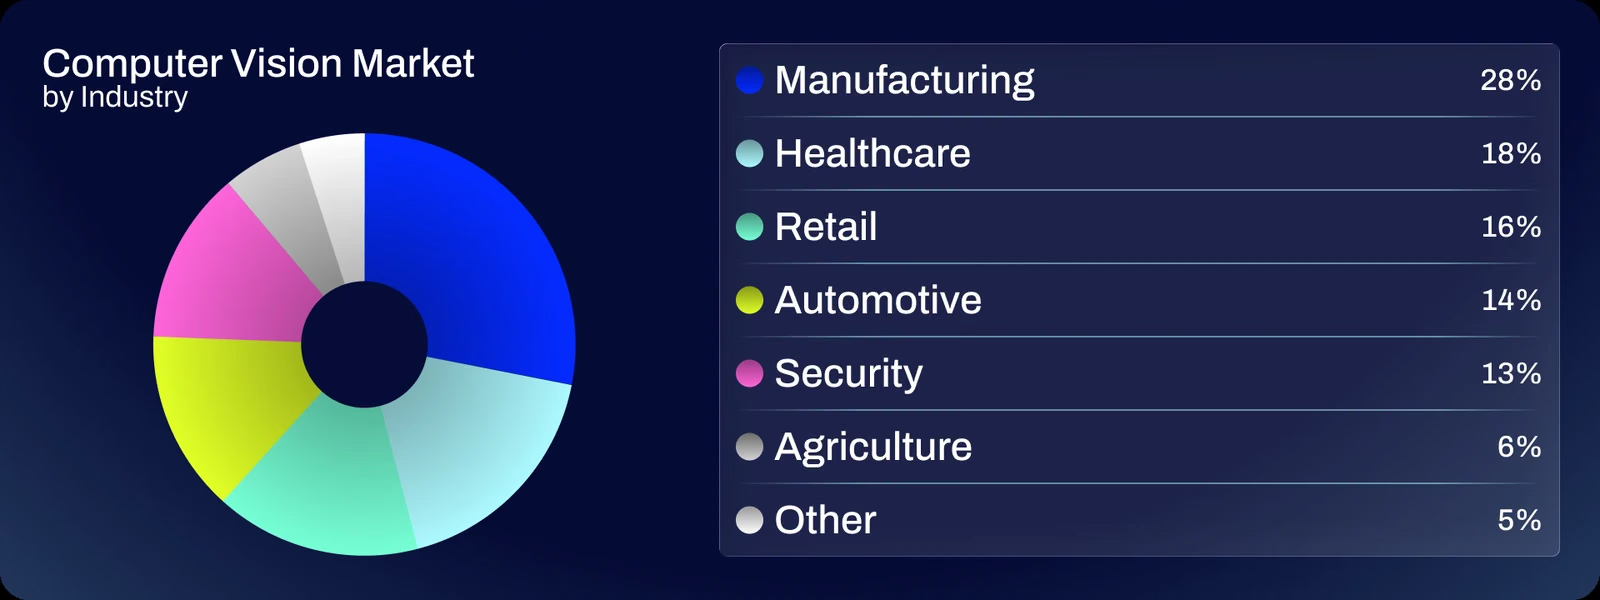
- Manufacturing: cameras inspect every part at line speed for cracks, scratches, and misaligned components, and track wear on machinery before it fails.
- Medical imaging: models flag tumors, fractures, and retinal disease in X-rays, CT scans, and retinal photographs for radiologists to review.
- Autonomous vehicles: cars detect lanes, signs, pedestrians, and other vehicles in real time and fuse camera output with radar and LiDAR into a 3D model of their surroundings.
- Retail: shelf cameras detect empty facings and misplaced products, and checkout-free stores track which items each shopper takes.
- Agriculture: drones and sprayers tell crops from weeds plant by plant, so herbicide and fertilizer go only where they are needed.
- Security and smart cities: systems count people and vehicles, monitor traffic flow, and use anomaly detection to flag unusual events in restricted areas.
Challenges and Limitations#
A model is only as good as its training set, and data labeling, drawing boxes or masks on thousands of images, often takes more effort than training the model itself. Conditions also change after deployment: rain, glare, night lighting, occlusion, or a moved camera shift the input away from what the model saw in training. Data augmentation simulates these conditions during training, and validation on held-out images catches overfitting before release.
Compute is the next constraint. Cameras, drones, and phones run models within tight power and memory budgets, so edge AI deployments favor small models and model quantization to reach real-time speed without sending video to the cloud.
Systems that analyze people raise bias and privacy concerns. A dataset that underrepresents some groups produces a model that performs unevenly across them, and face and body data count as sensitive personal data in most privacy laws. Since February 2025, the EU AI Act has banned real-time remote biometric identification in publicly accessible spaces for law enforcement, apart from narrow exceptions such as searching for victims of abduction or preventing an imminent terrorist threat.









