Kimi K3.1 Pro is now available for auto-annotation in Ultralytics Platform
Kimi K3.1 Pro from Moonshot AI is now in Ultralytics Platform. It scored 0.444 mAP50 on our VLM Leaderboard, a third above Kimi K3, and ranks 7th of 29 models.
Moonshot AI released Kimi K3.1 Pro on October 23, 2026, and it's available for auto-annotation in Ultralytics Platform today. We ran it through the same test as every other model on our VLM Leaderboard: 360 images from 36 real-world detection datasets.
Kimi K3.1 Pro scored 0.444 mAP50, a third higher than Kimi K3 (0.334), and ranks 7th of 29 models, ten places above its predecessor. Every model ranked above it is a closed model from Google, Anthropic, or OpenAI.
What's new in Kimi K3.1 Pro#
Kimi K3.1 Pro is the first model in Moonshot's K3.1 series, and Moonshot calls it its most capable 3T-class open-weight model to date. It's a post-trained version of Kimi K3, built with substantially more post-training compute, with a 1-million-token context window and image and video input. It always reasons before it answers, and Moonshot plans to release the full weights by November 4, 2026. Moonshot's announcement covers its coding, finance, and hallucination results.
Moonshot also lowered the price. Kimi K3.1 Pro lists at $2 per million input tokens and $10 per million output tokens, down from $3 and $15 for Kimi K3.
Kimi K3.1 Pro for auto-annotation in Ultralytics Platform#
Kimi K3.1 Pro joins the class-prompted vision language models in the Ultralytics Platform annotation editor. On an object detection dataset with 1–200 classes, it looks at each image and returns bounding boxes for the instances of your dataset's classes it finds, which you review and save like any other prediction.
You can use it in two ways:
- One image at a time: In the annotation editor, switch to Smart mode, select Kimi K3.1 Pro under Kimi in the model picker, and click Predict (or press
P). - A whole dataset: Run Batch Annotation from More actions > Batch Annotation on the dataset page to label every unlabeled image in a single run.
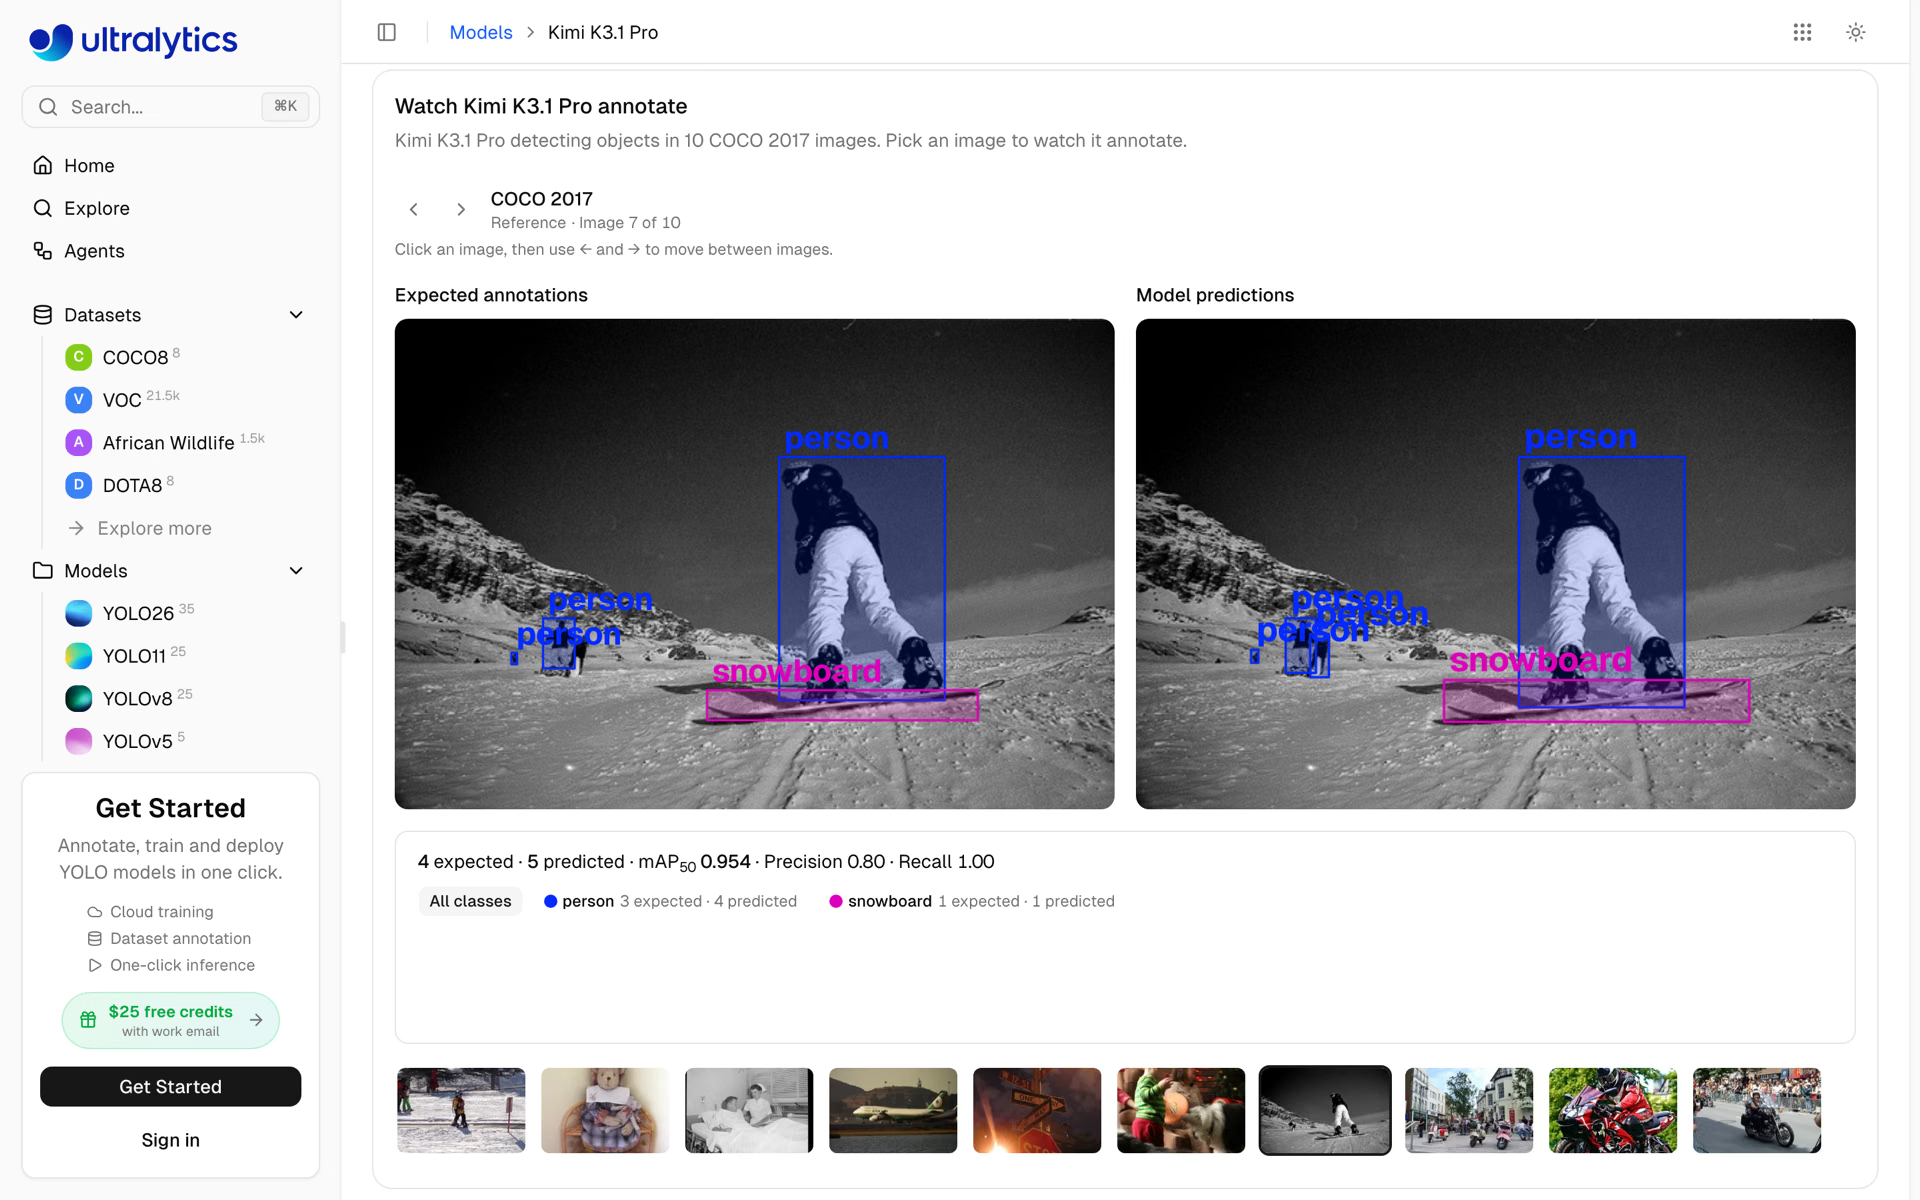
To see it work before you add a key, open the Kimi K3.1 Pro model page on Ultralytics Platform. It replays Kimi K3.1 Pro's recorded predictions on 10 COCO images next to the expected boxes, and shows its score on every benchmark dataset.
How we benchmarked Kimi K3.1 Pro#
A model that finds nearly every object in everyday photos can still miss most of them in a medical scan or a circuit board. So every model on the VLM Leaderboard takes the same frozen test, UL37 v2: 10 labeled images drawn at random from each of the 36 detection datasets in UL37, a set of real-world benchmark datasets Ultralytics uses for evaluation. They span medical imaging, aerial and satellite imagery, PCB inspection, security X-ray, retail shelves, traffic, sports, underwater scenes, thermal footage, and more.
Each image goes through Ultralytics Platform's production annotation pipeline with its dataset's class names, exactly as Smart mode and Batch Annotation call it, including the SAM 3.1 step that tightens each model's boxes. We score the boxes with the Ultralytics package's own detection metrics and average the 36 datasets equally. The VLM Leaderboard methodology has the details.
One setting is different for Kimi. Kimi K3.1 Pro defaults to Moonshot's maximum reasoning effort. At max, Kimi K3 ran past Ultralytics Platform's 115-second limit on about 40% of images in our tests, so Ultralytics Platform runs every Kimi model at high reasoning effort instead. Kimi K3 and Kimi K3.1 Pro were both benchmarked that way.
Kimi K3.1 Pro vs. Gemini 4 Argon, Claude Opus 5.5, and GPT-6 Astra#
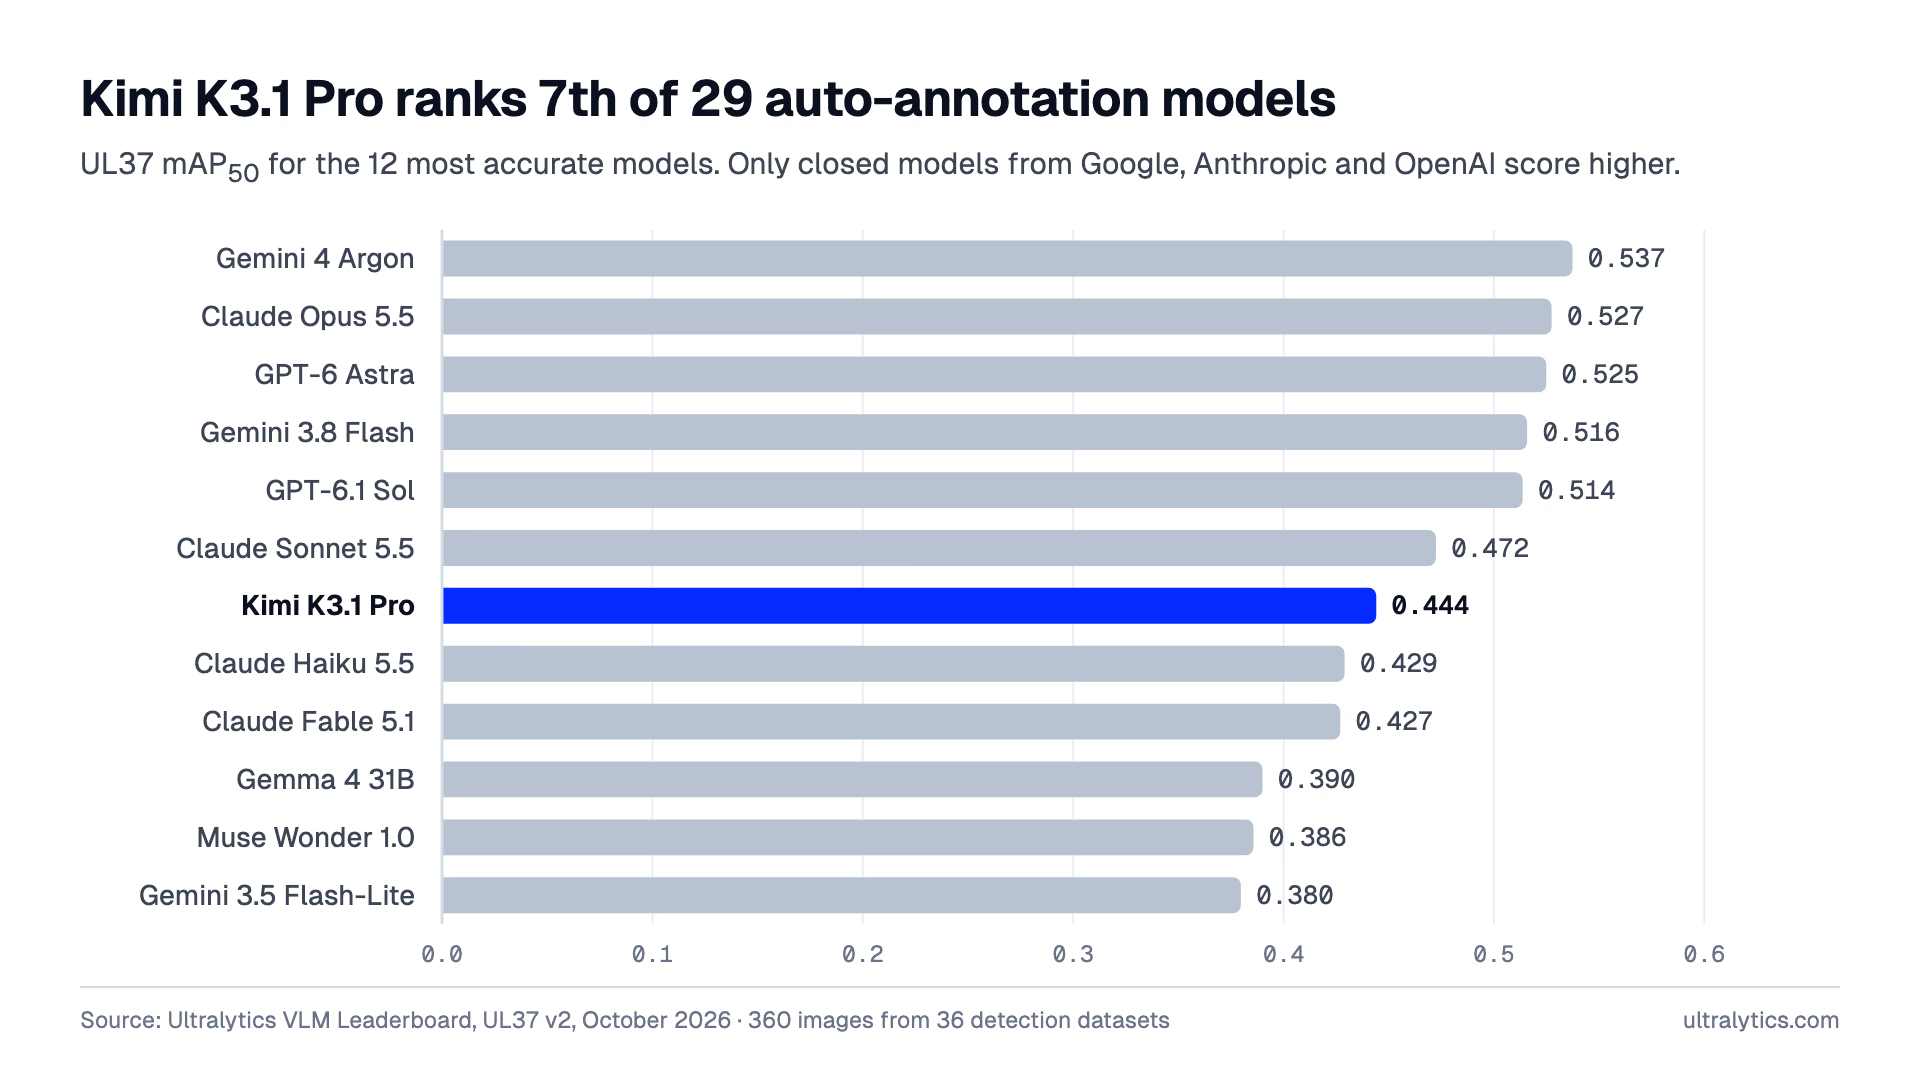
Kimi K3.1 Pro scored 0.444 mAP50. Gemini 4 Argon (0.537), Claude Opus 5.5 (0.527), GPT-6 Astra (0.525), Gemini 3.8 Flash (0.516), GPT-6.1 Sol (0.514), and Claude Sonnet 5.5 (0.472) scored higher, and it finished ahead of Claude Haiku 5.5 (0.429), Claude Fable 5.1 (0.427), and every open-weight model we run on our own GPUs, led by Gemma 4 31B (0.390), which isn't yet offered in Ultralytics Platform.
Both halves of the score improved. Precision rose to 0.560 from Kimi K3's 0.439, and recall rose to 0.483 from 0.376, so a larger share of its boxes were correct and it found more of the labeled objects.
Kimi K3.1 Pro vs. Kimi K3: where the upgrade shows#
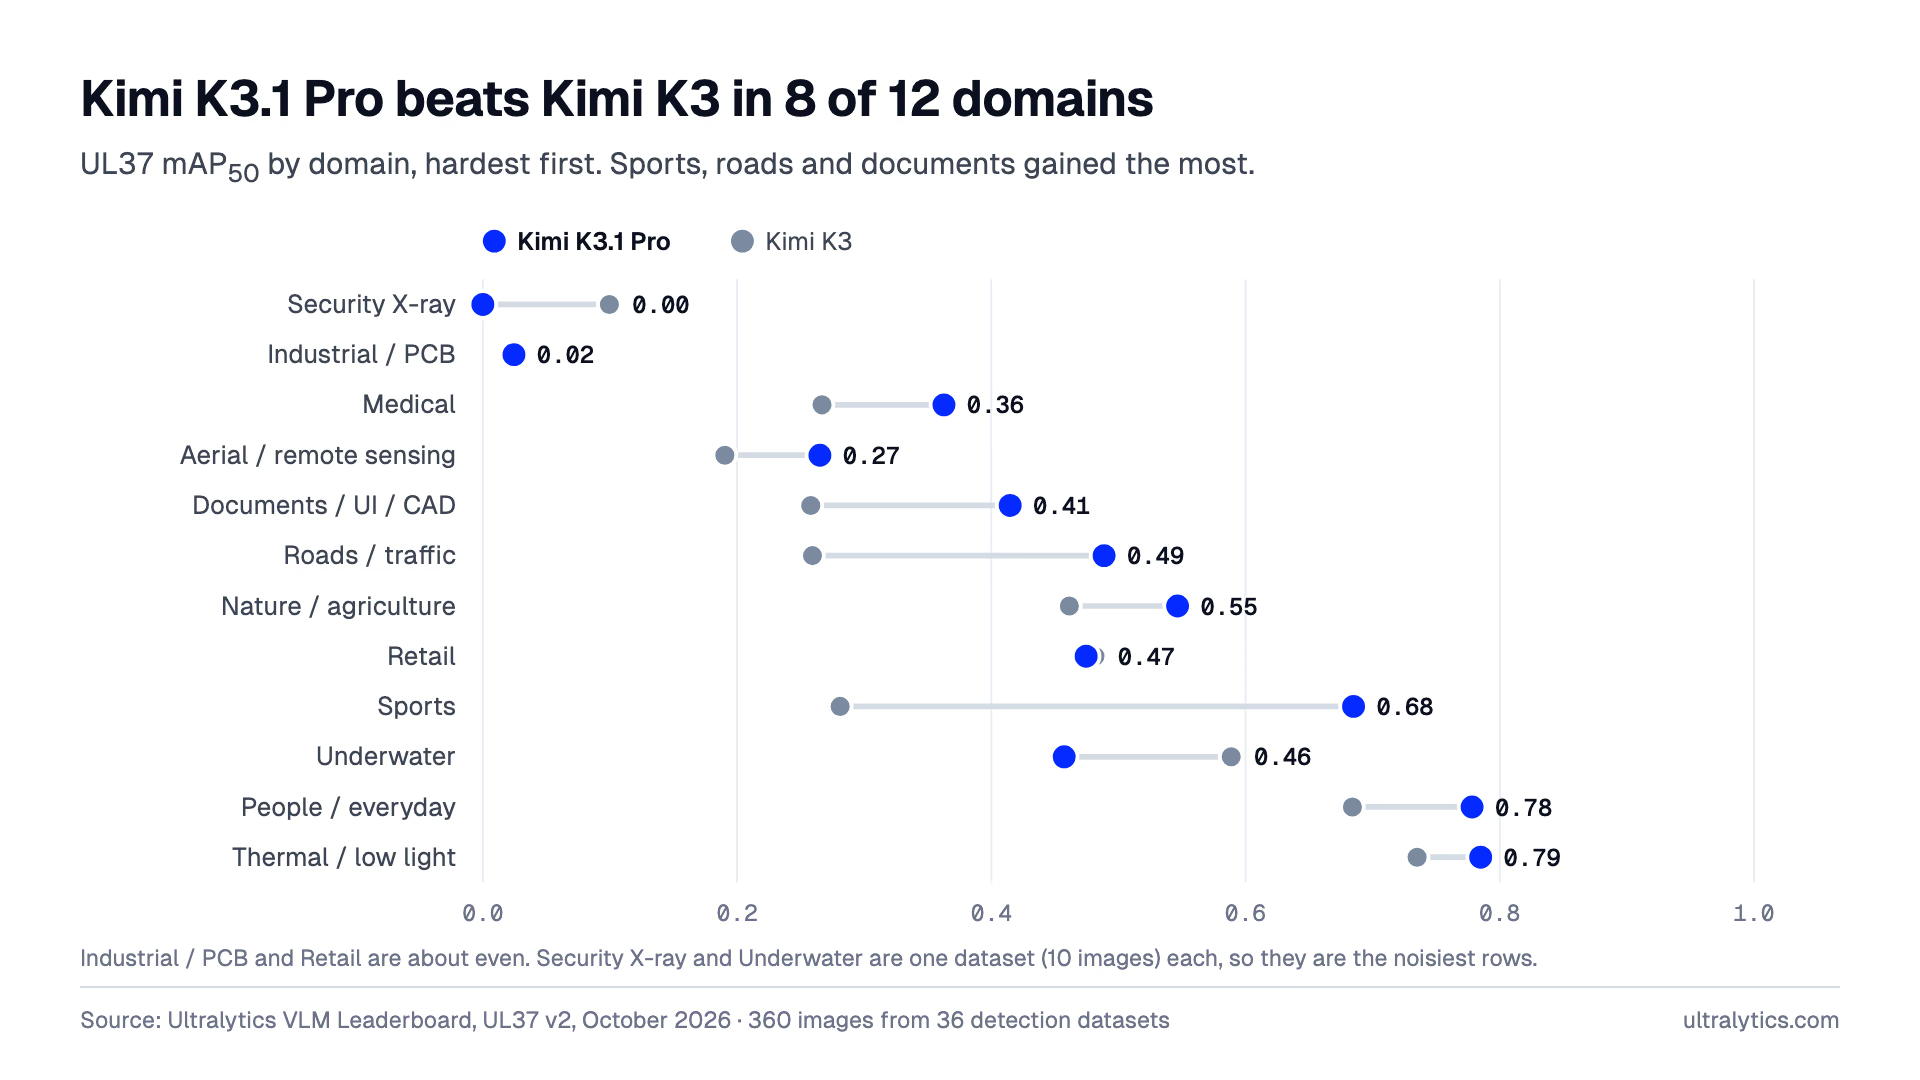
Kimi K3.1 Pro improved on Kimi K3 on 25 of 36 datasets and in 8 of 12 domains. The biggest gains came in sports (0.68 vs. 0.28), roads and traffic (0.49 vs. 0.26), and documents, UI, and CAD (0.41 vs. 0.26). On tennis balls it went from 0.08 to 0.74 mAP50, tying Gemini 3.8 Flash for the top score on that dataset, and on CeyMo road markings it went from 0.17 to 0.80.
In sports, Kimi K3.1 Pro also beat Gemini 4 Argon (0.68 vs. 0.60), and it outscored Argon on six datasets in all, including tennis balls, soccer, wheat heads, and thyroid ultrasound.
Not every domain moved up. Underwater and security X-ray (one dataset each) fell, retail slipped slightly (0.47 vs. 0.48), and industrial PCB defects stayed near zero for both Kimi models. Specialized imagery is still hard for every model, so treat Kimi K3.1 Pro's boxes as a first draft for human-in-the-loop review, and check a few predictions on your own images before you annotate a full dataset.
Accuracy, cost, and speed#
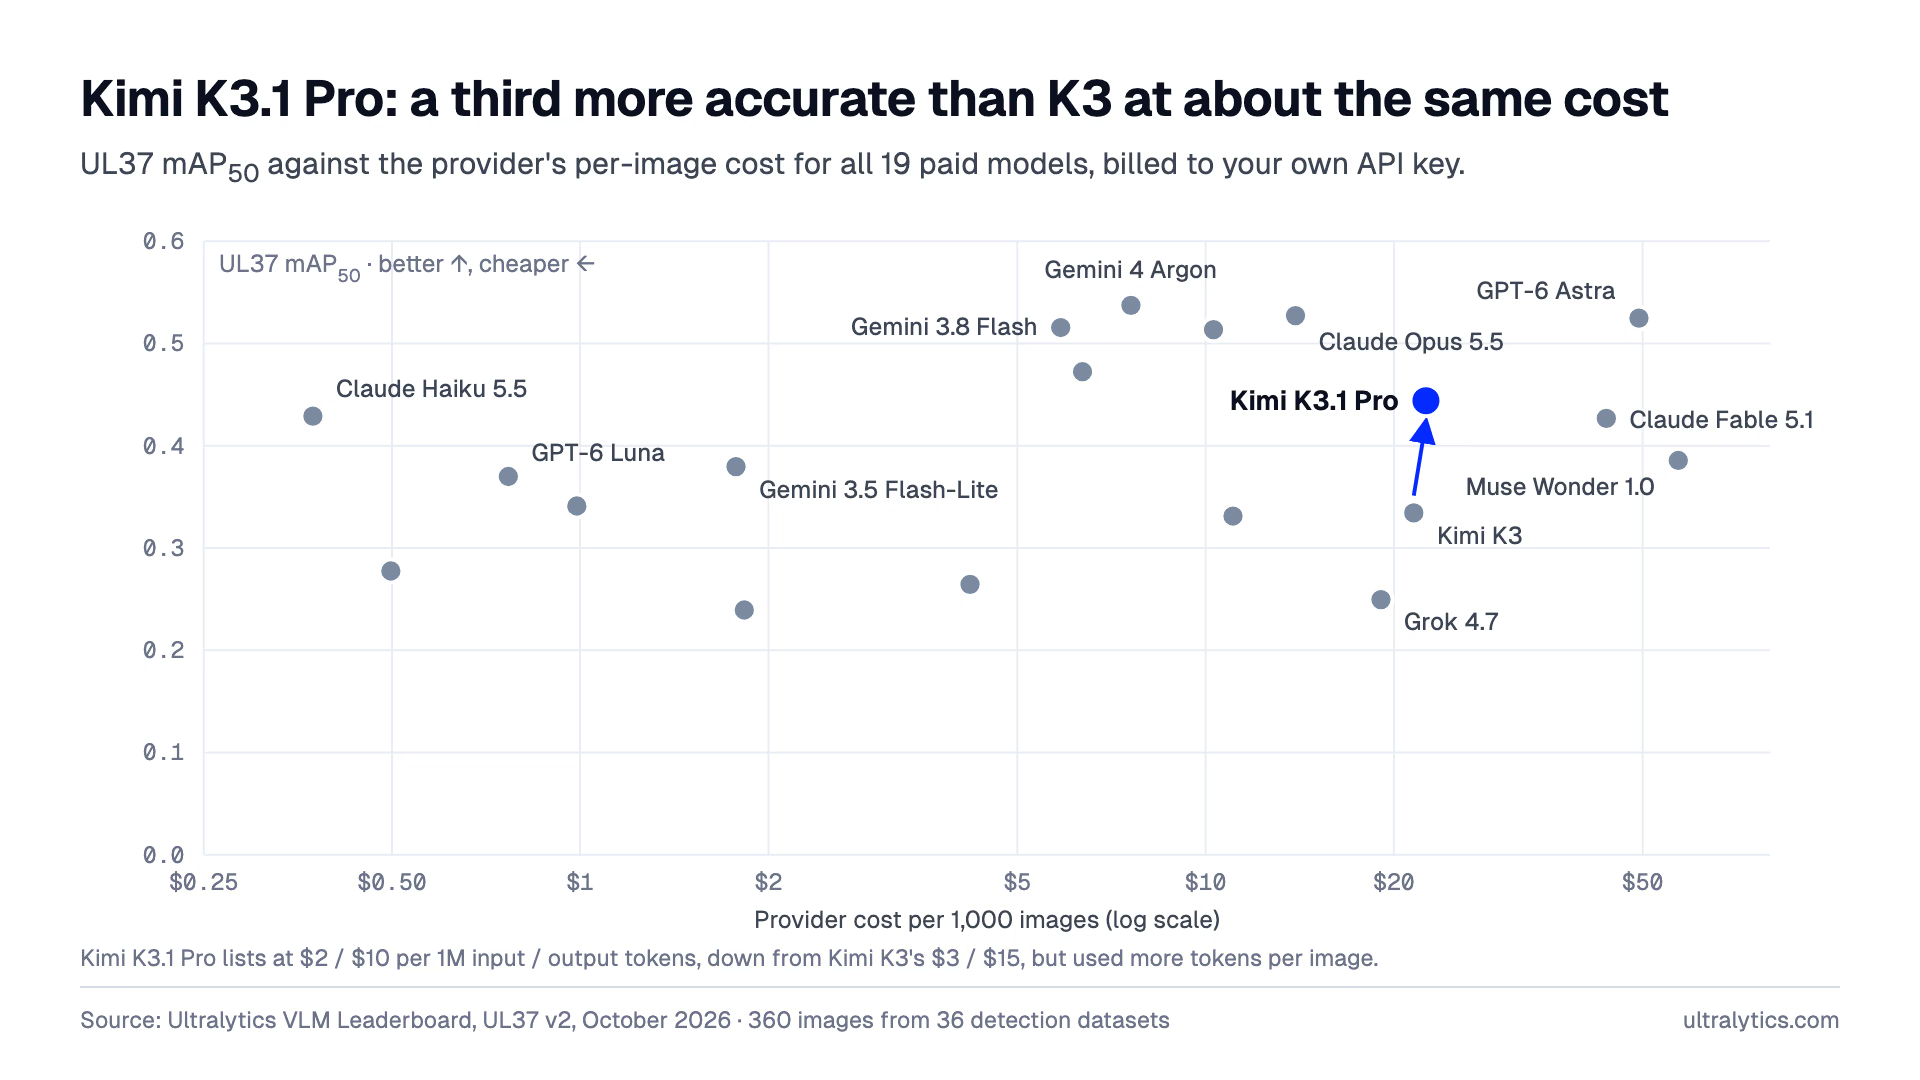
Paid models run on your own provider API key, so the provider bills each prediction directly. In our benchmark, Kimi K3.1 Pro cost about $22.50 per 1,000 images, close to Kimi K3's $21.50. Its token price is a third lower, but it used more tokens per image, so the upgrade buys about a third more accuracy for roughly the same bill.
It isn't the cheapest way to that accuracy. Five of the six models ranked above it cost less, including Gemini 4 Argon (about $7.60 per 1,000 images) and Claude Opus 5.5 (about $13.90), and Claude Haiku 5.5 came within about 0.015 mAP50 of Kimi K3.1 Pro at about $0.37 per 1,000 images.
Kimi K3.1 Pro also takes its time. Its median request took about 22 seconds per image, against 4.6 seconds for Gemini 4 Argon and 2.7 seconds for Claude Opus 5.5, and 6.4% of its requests didn't finish within Ultralytics Platform's 115-second limit, up from 1.7% for Kimi K3. A timed-out image comes back with no boxes, and you can predict it again. Moonshot also offers Kimi K3.1 Pro Highspeed, which it says runs two to three times faster with the same capabilities; Ultralytics Platform offers the standard Kimi K3.1 Pro.
Get started with Kimi K3.1 Pro in Ultralytics Platform#
- Create an API key on the Kimi API Platform, then add it in Settings > API Keys of the workspace that owns your dataset, or ask the workspace owner to add one (see how).
- Open a detection dataset in Ultralytics Platform, switch the annotation editor to Smart mode, and select Kimi K3.1 Pro under Kimi.
- Click Predict to label the current image, then review, adjust, and save the boxes.
- When the results look right, run Batch Annotation to label the rest of the dataset.
Batch Annotation adds the standard Ultralytics Platform processing fee of $1.00 per 1,000 images, separate from what Moonshot bills your API key. Each run saves a dataset version first, so you can always roll back.
Once your dataset is labeled, train an Ultralytics YOLO26 model on it in the same workspace (see the training docs). To compare Kimi K3.1 Pro with the leader, read our Gemini 4 Argon auto-annotation post, or browse every model on the VLM Leaderboard and the Ultralytics Platform model pages. Then sign in to Ultralytics Platform to try Kimi K3.1 Pro on your own data.
Frequently asked questions
Kimi K3.1 Pro is the flagship of Moonshot AI's Kimi K3.1 series, released on October 23, 2026. It's a post-trained version of Kimi K3 with a 1-million-token context window and image and video input, and Moonshot plans to release its weights by November 4, 2026. In Ultralytics Platform, it's available as a class-prompted auto-annotation model that draws bounding boxes for your dataset's classes.
Yes. On our VLM Leaderboard, Kimi K3.1 Pro scored 0.444 mAP50 against 0.334 for Kimi K3, improved on 25 of 36 datasets, and cost about the same per image ($22.50 vs. $21.50 per 1,000 images). Its median request was slightly faster, but it timed out more often (6.4% vs. 1.7% of requests).
Gemini 4 Argon (0.537 mAP50) and Claude Opus 5.5 (0.527) were more accurate, faster, and cheaper per image in our benchmark. Kimi K3.1 Pro (0.444) ranks 7th of 29 models, behind only closed models from Google, Anthropic, and OpenAI, and it outscored Gemini 4 Argon on six datasets, including tennis balls, soccer, wheat heads, and thyroid ultrasound.
Moonshot bills your own API key at $2 per million input tokens and $10 per million output tokens, which came to about $22.50 per 1,000 images in our benchmark. Batch Annotation also adds the Ultralytics Platform processing fee of $1.00 per 1,000 images.
Yes. Hosted models such as Qwen3.8 27B, Gemma 4 26B, and SAM 3.1 Text run on Ultralytics Platform with no provider key, and you can also auto-annotate with pretrained or your own fine-tuned Ultralytics YOLO models.









